* Equal technical contribution.
Converting a real interaction into a simulation usually means hand-tuning models and aligning coordinate frames by hand, once per scene. This work replaces that with vision-language agents that recover geometries, object states and physical parameters directly from the recording.
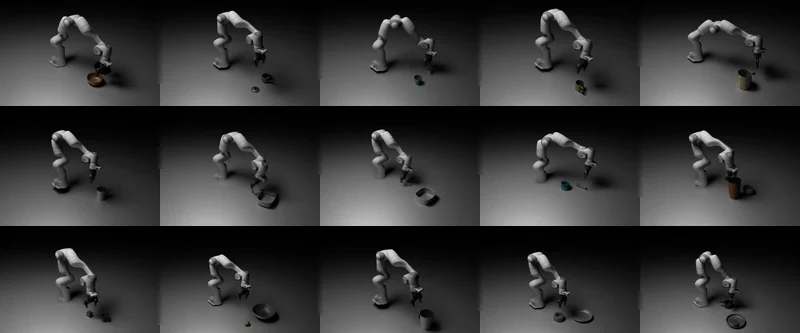
One pipeline covers rigid-object manipulation, deformable-object interaction and humanoid motion — cases that previously needed separate, specialised Real2Sim methods. An open-weight VLM backend reaches success rates comparable to frontier models, which makes the pipeline cheap enough to run at dataset scale. The resulting twins are used downstream for policy learning and for evaluating policies against something that behaves like the world did.
Videos, an interactive scene viewer and the 25-episode DROID gallery are on the project site.